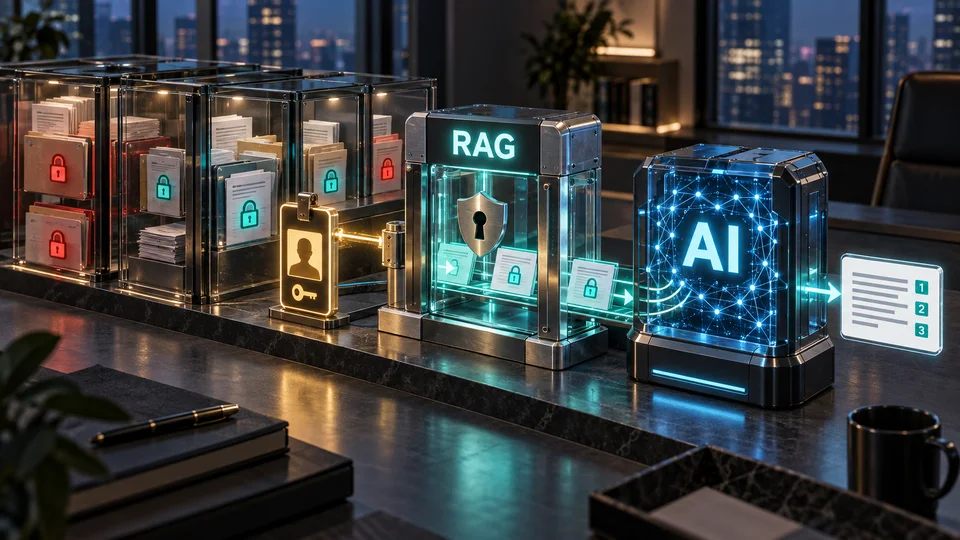
A user asks an enterprise assistant, “Why did this project’s budget change?” The answer is accurate, well sourced and convincing. There is one problem: one of its sources was a set of meeting minutes the user was not allowed to read. This hypothetical example shows why answer quality and correct enforcement of access permissions need separate evaluation in a RAG system.
Better embeddings may find a more relevant document, but relevance does not establish permission. The system has to answer both “What is relevant to this question?” and “Which parts is this user entitled to see right now?” Cohere’s announcement of Compass Cloud on 25 September 2026 offers a reason to examine that boundary. It does not establish that one product solves every security problem in RAG.
Permissions must take effect before content enters the answer pipeline
In a simple implementation, the application retrieves a few close matches and then removes unauthorized results from the list. That filter can contribute to the system’s defenses. But if the text has already reached a reranker, a log, a shared cache or the generative model, removing it from the final answer does not undo the earlier exposure. There may also be so few authorized documents among the top results that the answer becomes unnecessarily incomplete.
Enforcing permissions during retrieval means restricting the search scope and the passage of content according to a verified user identity, the tenant and the current access policy. A role identifier must not be just a string the user writes in a prompt; the application needs to obtain it from a trusted authentication and authorization source. Implementation details depend on the search engine and data structure. The presence of a “filter” option alone does not demonstrate that this boundary is enforced correctly.
For retrieval across multiple steps, permission checks at the first stage are insufficient. Every subsequent search and every document reached through links in an earlier document must remain within the same authorized scope. The context sent to the model must pass through those controls as well. These are architectural and testing considerations, not a claim that all these details have been verified in Compass.
Caching is another important case. Both the cache key and the validity of a cached answer need to account for the tenant, the access scope and changes in permissions. After access is revoked or a document is deleted, an old answer must not become an alternative route for disclosing its contents. Reranking and logging raise the same questions: which service sees the raw text, under what permission, and for how long does it retain it?
What has Compass Cloud announced?
In its introduction to Compass Cloud, Cohere describes a managed retrieval platform that brings source connections, document processing, embeddings, indexing, retrieval and reranking into one pipeline. According to that announcement, tenant and document restrictions are applied during retrieval, and access is available through an API, a Python SDK and MCP. These are the capabilities stated by the provider. This article does not report an independent security or operational test of the service.
The announced Cloud offering is a private beta for a limited number of enterprise partners. The announcement also discusses a self-hosted offering for regulatory and privacy requirements. Features, access conditions and responsibilities in the managed version should therefore not be assumed to apply unchanged to an internal deployment. Self-hosting does not, by itself, mean open source, free of charge or independent of support arrangements.
Here, MCP is an interface for connecting tools. Using that interface does not guarantee confidentiality: where a tool runs, how it authenticates users, the scope of its permissions, what it logs and where it sends data remain decisive. Similarly, ensuring that a user sees only authorized documents does not answer a different question: has the organization authorized sending those documents to a cloud provider for processing?
Read the retrieval score alongside its conditions
In the internal HighFinance evaluation reported by Cohere in the same announcement, the displayed nDCG@10 score rises from 64.8 to 81.1: an increase of 16.3 points on the reported scale. The dataset consists of financial documents and internally labeled questions, and the document ingestion paths were not identical. In the Azure Search comparison, GPT-4.1 Mini handled parsing, while the Embed 4 pipeline received PDFs directly as images. The result cannot therefore be attributed solely to differences in embeddings.
The report can suggest a hypothesis to test: preserving visual information and document structure may improve retrieval for some documents. It does not establish general superiority across organizations, retrieval quality in Persian or correct enforcement of access control. To separate the effect of the retrieval engine from document processing, one comparison needs identical preprocessed inputs. A comparison of the complete stacks, using different parsing methods, should be reported separately.
What still needs to be clarified for an enterprise decision?
The announcement reviewed here is not a sufficient basis for firm conclusions about pricing, SLAs, hosting regions, data residency or service availability in Iran. That limitation should not be turned into a claim that none of the company’s documents or contracts contains this information. Buyers need the documentation applicable to their particular plan and customer arrangement. Until actual availability and terms of service are clear, this article does not recommend Compass Cloud as the default practical choice for an Iranian organization.
Before selecting any stack, a procurement team can ask for a small but specific acceptance test: have two users with different permissions ask the same question, then revoke one user’s access and delete a document. The system must honor those changes in fresh retrieval, cached answers and questions requiring multiple retrieval steps. The test should inspect both the retrieved document chunks and the final answer. A harmless-looking answer is insufficient evidence, because unauthorized content may already have entered the model’s context or another service.
The selection criteria must bring together retrieval quality, response time, cost and enforcement of access boundaries. If accurate text comes from an unauthorized document, a high retrieval score does not solve the problem. Removing every result and giving no answer is not a useful outcome either. That balance needs to be evaluated with authorized test documents, defined roles and acceptance criteria set in advance.