Published 25 October 2026 · 16 min
Archive
Articles
Technical articles, essays and historical notes, selected for English readers.
All topics and categories
Archive layout
Page 1 / 4 · 46 articles
AI infrastructure Published 17 October 2026 · 14 min
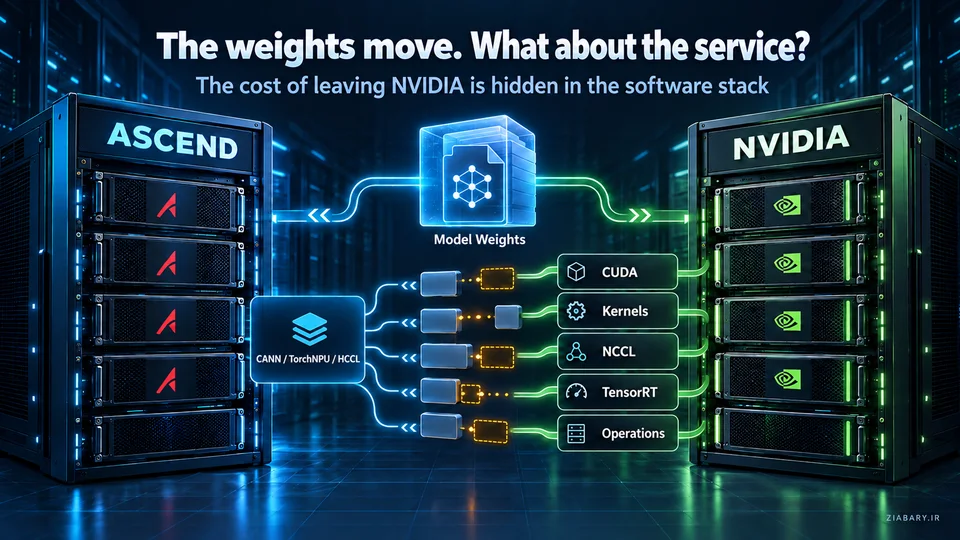
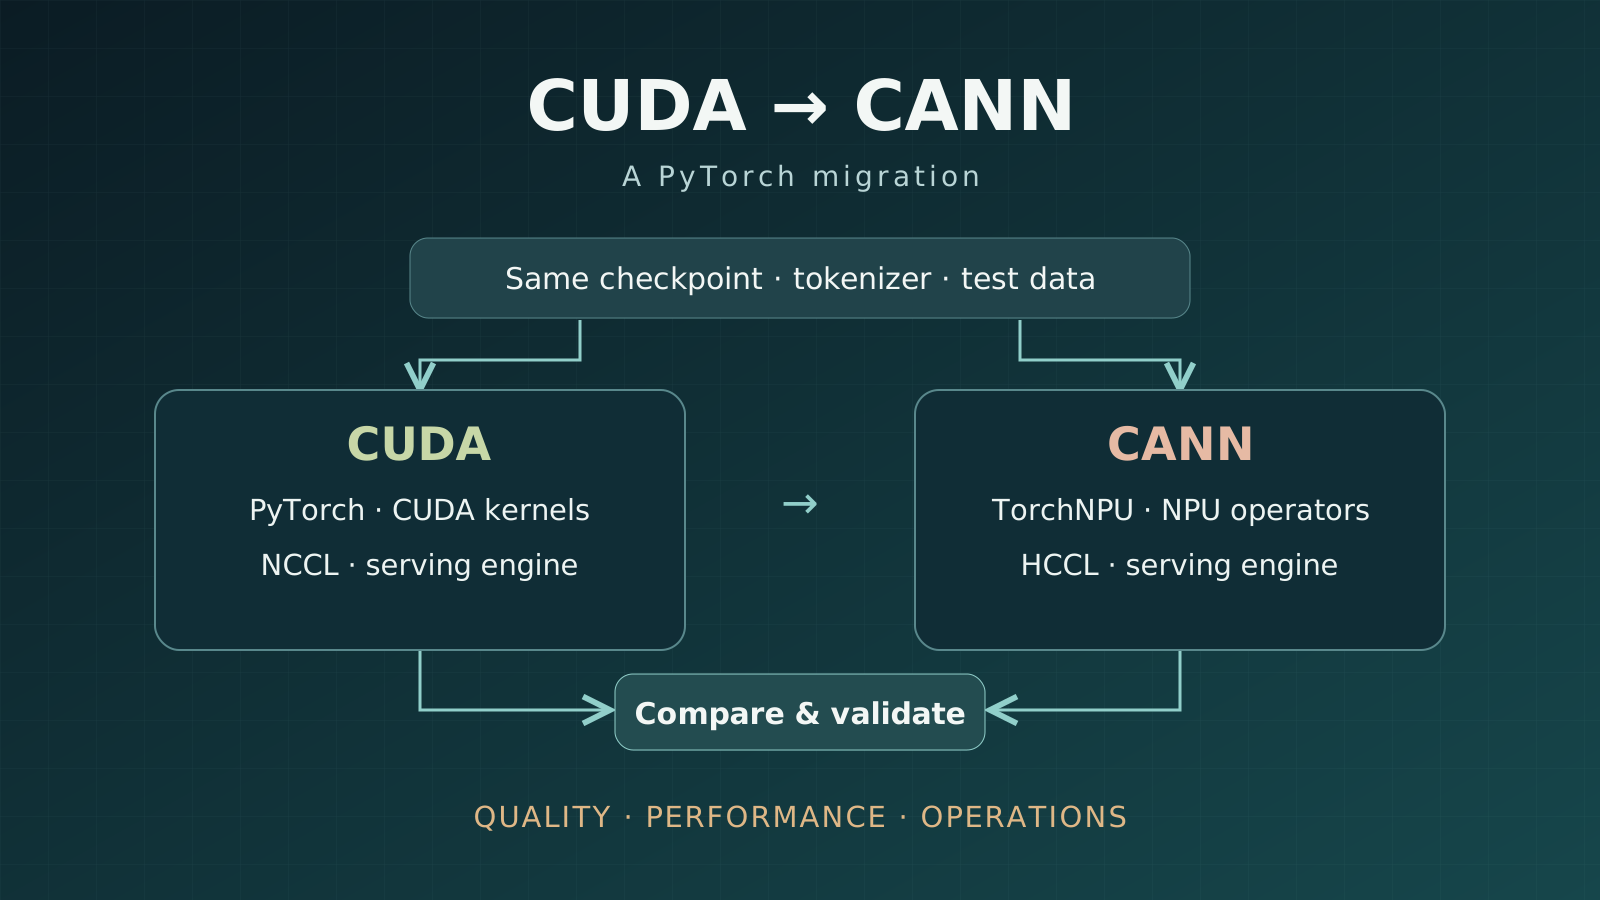
What breaks if we remove NVIDIA tomorrow?
CUDA is more than a library. Kernels, multi-GPU communication, inference engines, operations and team expertise all contribute to the cost of moving an NVIDIA-based service to Ascend. Read article →
AI infrastructure Published 13 October 2026 · 18 min
What do 100 concurrent users mean for an AI assistant?
User count alone does not define an AI assistant’s capacity. Worked examples and an interactive tool connect request rates, token lengths, queues and KV cache to GPU selection and acceptance testing. Read article →
Language models Published 15 September 2026 · Updated 11 October 2026 · 13 min
Ollama, vLLM, SGLang or llama.cpp: choosing an inference engine
How scheduling, KV cache, model formats and operational controls change the choice of inference engine, with a worked memory example and a reproducible comparison method. Read article →
Industrial AI Published 10 October 2026 · 11 min
What does 95 percent accuracy mean for a factory?
Two inspection systems can both report 95 percent accuracy and produce very different results on a production line. How do we turn that percentage into error costs and acceptance criteria? Read article →
AI infrastructure Published 7 October 2026 · 21 min
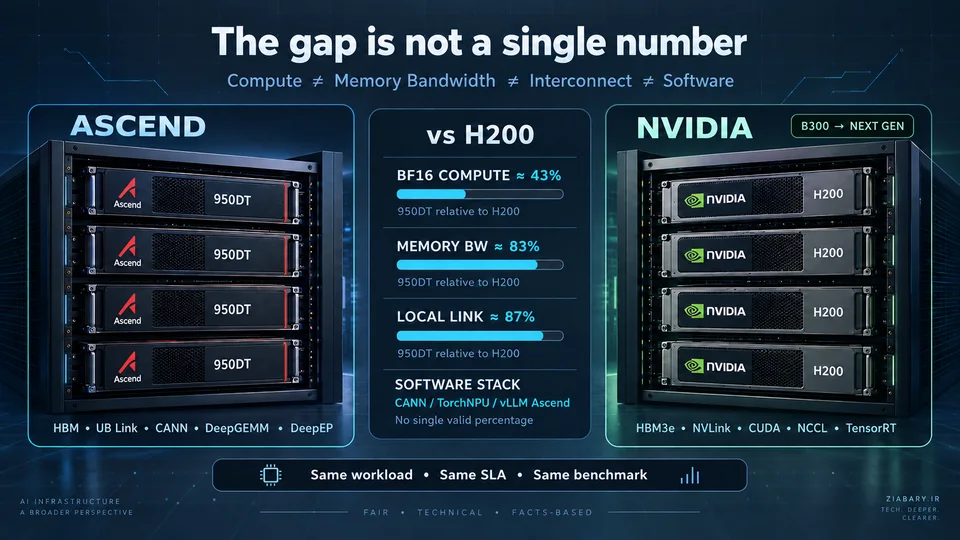
Ascend vs NVIDIA: how large is the real performance gap?
From Ascend 910C and 950PR/DT to H200 and B300: comparing equivalent specifications, memory, kernels, interconnects, serving software and operating costs. Read article →
Language models Published 29 September 2026 · 7 min
When an open-weight model builds exploits: where does defense become attack infrastructure?
What do the NIST and Anthropic assessments of GLM-5.3 tell us, and what should change when a team gives a coding agent access to tools? Read article →
Product and business Published 26 September 2026 · 12 min read
An AI contract: what exactly should we receive?
A model or a working demo is not a complete AI project deliverable. A practical guide to acceptance criteria, data, testing, security, operations, version changes and the ability to leave a supplier. Read article →
Artificial intelligence Published 26 September 2026 · 7 min read
Enterprise RAG needs more than embeddings: access control belongs in retrieval
A correct answer can come from a document the user has no permission to read. The Compass Cloud announcement provides a starting point for examining access control in retrieval and its distinction from where data is processed. Read article →
AI infrastructure Published 19 September 2026 · 18 min
Where does GPU confidential computing overhead come from?
Why does one confidential B200 inference stack lose 39% of throughput while another incurs only a few percent? A close reading of the measurements: command submission, PCIe, encrypted NVLink and the serving software. Read article →
Language models Published 16 September 2026 · Updated 19 September 2026 · 13 min
The real cost of running an LLM: buy hardware, rent a GPU or use an API?
A worked USD scenario for API usage, GPU rental and ownership, including retries, accepted answers, operations, energy and conditional break-even calculations. Read article →
Language models Published 2 September 2026 · Updated 19 September 2026 · 12 min