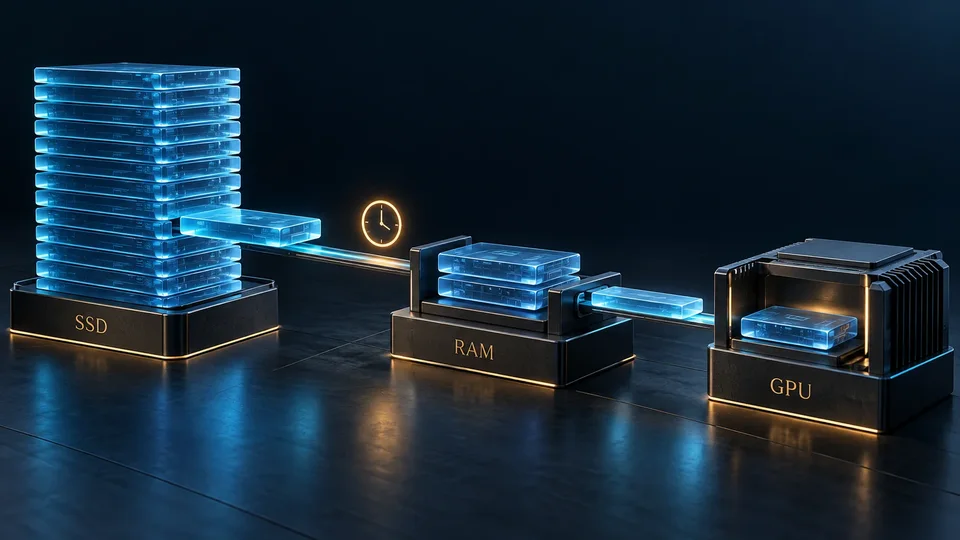
Running a 70 billion parameter model on a GPU with only a few GiB of memory sounds like removing a major infrastructure expense. AirLLM makes that possibility worth examining, but the key distinction is between being able to execute the model and finishing useful work in time. The weights do not disappear: much of their storage moves outside the GPU, and execution must bring the required data back.
That can be valuable for research, occasional use of existing hardware or a job with a flexible deadline. For an interactive assistant, transfer time and lost serving capacity may cost more than the memory saved. Compare layer-wise execution with a smaller resident model, quantization, mixed CPU/GPU execution and model partitioning. The language-model guide presents those as distinct execution strategies.
How a large model passes through a small GPU
In conventional resident inference, weights stay in VRAM and are reused for prompt processing and generation. In layer-wise execution, only the required portion is loaded, computed and released before the next portion. The idea, also described in ZeRO-Inference, exchanges GPU residency for host memory or storage capacity and data movement.
The inspected AirLLM implementation attaches loading and eviction around module execution while Transformers drives generation. Some modules may remain resident. Consequently, peak VRAM includes more than one abstract layer: intermediate state, workspace and the selected cache policy also matter.
The project’s headline example of a 70B model with about 4 GB VRAM describes a low-residency execution possibility. It is not a complete service specification. Architecture, input and output lengths, cache and weight representation can change the requirement.
Memory moves elsewhere
A hypothetical model with exactly 70 billion sixteen-bit weights needs 140 GB, or about 130.4 GiB, for raw weights alone. If all weights are to remain available in host RAM, 128 GiB is insufficient even before the operating system and application use memory. A disk-backed route may need less RAM, but repeated reads then enter the processing path.
SSD capacity can exceed the original download. Keeping both source weights and prepared layer files may approach twice the weight volume if preparation creates a full second copy. That is not a universal multiplier: compression, links and reused files change it. AirLLM’s weight preparation code includes linking/copying paths and an option to delete original files after conversion. Plan the preparation peak as well as the final footprint.
VRAM must still accommodate the largest active portion, intermediate data, KV and computation workspace. SSD throughput, host-memory bandwidth and the transfer path can dominate. A faster GPU does little for a pipeline that leaves it waiting for weights; the server platform components therefore matter directly.
“Larger than VRAM” covers different execution methods
Offload sometimes means keeping weights on the CPU side and moving them to the GPU for computation. In another system, part of the computation actually runs on the CPU. The distinction changes the bottleneck.
| Method | Placement and computation | Main resource to examine |
|---|---|---|
| One resident GPU model | Weights stay and execute in VRAM | Capacity, bandwidth and request headroom |
| AirLLM layer-wise execution | Portions arrive from host memory or storage as needed | Repeated transfers, loading and optional decompression |
| Accelerate CPU/disk offload | Offloaded module weights move to the execution device | Placement policy, transfers and host memory |
| Mixed llama.cpp execution | Some layers can execute on CPU, others on GPU | CPU compute and RAM bandwidth, plus the boundary transfer |
| A model split across GPUs | Resident partitions do not require repeated disk reads | Per-device capacity, interconnect and parallelism strategy |
The distinction follows the Accelerate offload documentation, llama.cpp’s execution options and vLLM’s parallelism guide. This is not a speed ranking. A model slightly larger than VRAM presents a different problem from one requiring several times that memory.
How often must the weights travel?
Ordinary autoregressive decode generates one new token per sequence per step. A dense model whose layer weights are discarded after each use needs those layers again for the next step. KV cache preserves context computations; it does not replace network weights. A long answer can therefore cause a large volume to cross the transfer path repeatedly.
Consider an educational transfer calculation, not an AirLLM benchmark. Assume the entire 140 GB of uncompressed dense weights moves from host to GPU on every decode step for one sequence, at an effective 20 GB/s. In the first two cases below, weights also have to be reread physically from SSD; in the third, they are available in RAM. The bandwidths are explicit example inputs, not specifications of a named device.
| Weight location | SSD read time per step | Host-to-GPU transfer per step | Optimistic floor with complete overlap |
|---|---|---|---|
| Full reread from SSD at 3.5 GB/s | 40 s | 7 s | At least 40 s |
| Full reread from SSD at 7 GB/s | 20 s | 7 s | At least 20 s |
| Ready in RAM; no physical SSD reread | 0 s | 7 s | At least 7 s |
Each time is volume divided by effective bandwidth. With perfect overlap, the pipeline cannot be faster than its slowest stage, so the last column is not the sum of the two preceding ones. Incomplete overlap, pipeline fill and drain, computation and cache transfers add time. Resident weights, batching, compression or selective expert loading change the transferred volume and invalidate a literal application of this example.
The same arithmetic gives a useful design bound. If the target gap between generated tokens were 0.2 seconds, a 20 GB/s path could carry at most 4 GB in that interval even before any other work. A much larger transfer requires less data movement, more reuse or a different latency target. Extra arithmetic capability alone cannot overcome that bound.
Prefill, output length and batching have different effects
During prefill, many prompt tokens can use a layer in one pass. During ordinary decode, output depends on successive steps. More work per weight transfer can improve aggregate throughput, while individual requests still wait a long time.
FlexGen illustrates this distinction with OPT-175B and four-bit compression: one reported setup uses a 16 GB T4, 208 GB RAM and a 1.5 TB SSD, with 512 input tokens and 32 output tokens. It reports 1.122 aggregate tokens/s, effective batch 144 and 4,072 seconds latency. In that compressed run, weights no longer needed disk offloading. Those figures are neither a per-user rate nor an AirLLM measurement.
KV remains another budget. For Qwen2.5-72B-Instruct, the model configuration specifies 80 layers, 8 KV heads and head dimension 128. With sixteen-bit KV, full attention and no shared prefix, raw bytes are:
2 × 80 × 8 × 128 × 2 × retained tokens × active sequences
| Active sequences | Retained tokens per sequence | Raw sixteen-bit KV |
|---|---|---|
| One | 2,048 | 0.625 GiB |
| One | 8,192 | 2.5 GiB |
| One | 32,768 | 10 GiB |
| Four | 8,192 each | 10 GiB |
If cache stays on the GPU, add it to active weights and workspace. A short demonstration on a small card therefore does not establish support for long-document RAG or several conversations. Transformers cache offloading can move this state in compatible configurations, adding another transfer stream. Model and engine support must match the selected cache implementation.
Compression and prefetch are not automatically additive
Prefetch prepares the next layer while the current layer computes. It reduces waiting when computation can hide enough of the load; a much slower transfer still sets the pace. More RAM can also keep files in the operating-system cache. A file located on SSD is not necessarily reread from the physical device at every access. Record cold and warm behavior separately.
In the inspected AirLLM revision, compression='4bit' uses NF4 for stored layer data and reconstructs values for computation after moving compressed data to CUDA. It does not turn every operation into four-bit arithmetic. That revision also disables general prefetch when compression is enabled; the two optimizations cannot simply be added together. The compression code and versioned loading implementation define this behavior.
Moving layers does not itself require deleting parameters or lowering precision. Compression adds a separate numerical approximation. Different execution paths need not produce bit-identical output, so assess task success rather than expecting identical prose. The four-bit quantization article separates weight size, compute precision, KV and quality.
Where layer-wise execution can be useful
Its strongest case is a workload where the larger model adds useful quality, memory prevents access and waiting is acceptable. Even “offline” needs a completion deadline: a nightly queue that does not finish by morning still lacks capacity.
| Workload | Role for layer-wise execution | Decisive comparison |
|---|---|---|
| Limited research with a large model | Useful access through existing hardware | Preparation and sample execution versus temporary high-memory access |
| Small extraction or data-generation job | Worth evaluating when a smaller model misses quality | Accepted outputs per hour and total completion time |
| Overnight document processing | Depends on batching and the size of the queue | Completion within the actual processing window |
| Multi-user interactive chat or RAG | Usually a weak starting point for a very large streamed dense model | Smaller resident model, retrieval quality and latency under demand |
| Coding agent with sequential calls | Each stage can accumulate transfer latency | End-to-end task time versus a resident specialist |
| Adapter experiments on supported architectures | A research possibility with the training implementation | Step time, time to target quality and repeated experiment cost |
For a document assistant, retrieval quality or a better-suited smaller model may improve the answer without streaming a much larger one. A resident 3B or 8B model can leave room for context and more active requests, while replicas on separate GPUs offer another scaling route. The model-size article and RTX 4090 comparison develop those alternatives.
Check the model path, not just the family name
AirLLM, Ollama and vLLM do not describe the same layer of a system. The memory technique discussed here does not supply every serving feature: queues, admission limits, context controls and load management remain relevant. Putting an HTTP API in front of a streamed model does not remove its transfer bound. The software table separates execution, serving and management roles.
Identify the original checkpoint, architecture, format and dependency versions. A GGUF download does not establish that the same file works in AirLLM’s Transformers-oriented checkpoint and layer-shard path. Its model-class selection code contains architecture-specific routes. A record saying only “Qwen” or “DeepSeek” cannot reproduce the configuration.
MoE adds another distinction. The inspected code has selective expert-loading paths for supported architectures. An active-parameter count alone does not determine transferred bytes: a batch may select more experts than one token, and resident expert reuse matters. The 140 GB dense example must not be applied indiscriminately to MoE. Total weights still determine full storage needs.
What about training?
Describing the reviewed revision as inference-only would miss its LoRA implementation. The code contains text-only routes for Qwen3.5/Qwen3.8 dense VL models and a Qwen4Exp route for Qwen3.8-Flash-Next. The vision component stays on meta; this is not image training. Frozen base weights stream layer by layer, while adapters and their optimizer state remain on the GPU, with intermediate-state handling and backward recomputation reducing residency.
That is a version-specific code capability, not validation of every model supported for inference. It is also not full-weight training or pretraining a large model on a tiny card. Repeated transfers, recomputation and many training steps can make time-to-result substantial. Compare the cost of reaching the target quality and repeating experiments with temporary access to a larger-memory system.
Measure the completed job
Separate download and preparation from ordinary execution. Use representative inputs, one near the required context limit and a small but realistic queue. Record first-token time, continuation rate, whole-job duration and peak RAM/VRAM. Compare cold and warm runs to reveal dependence on host caching.
For interactive service, include expected concurrent demand, slow requests and queue growth. For offline work, cost per thousand accepted outputs can be clearer: infrastructure, energy and operating time divided by useful completed jobs. Lower instantaneous power does not establish lower energy per job when execution lasts much longer.
AirLLM has a clear role when the larger model provides useful quality, VRAM blocks access and the deadline can tolerate the transfer path. The hardware feasibility table helps compare that route with more memory, a smaller model or a different placement strategy, without calling a memory estimate a speed measurement.