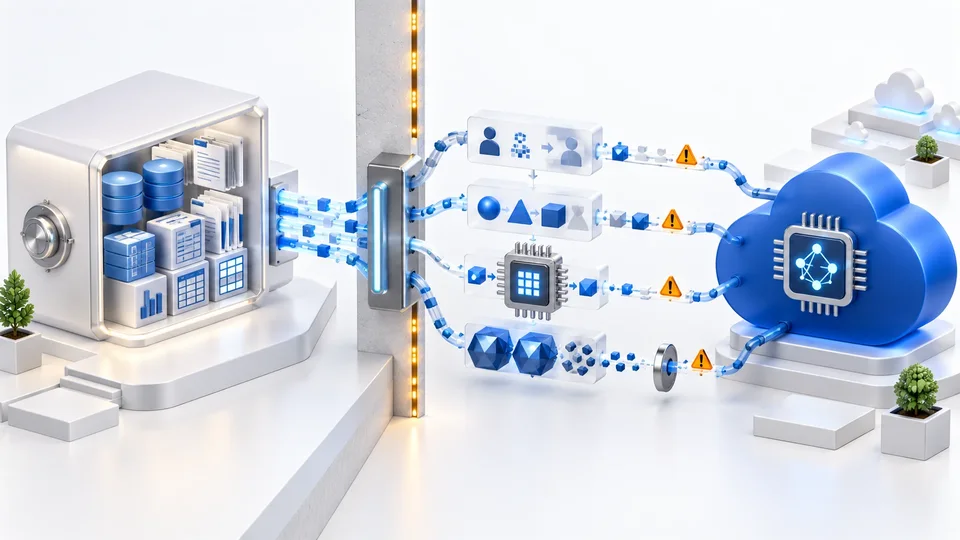
Publicly available language models give organizations capabilities ranging from contract and financial report analysis to customer support and security incident investigation. Building an internal equivalent is not always feasible or economical. The problem begins when the quality of a model’s answer depends on seeing precisely the details the organization cannot allow to leave its control: people’s names, real figures, relationships between events, the logic of a process, the text of a contract, or even a question about a confidential project.
For a simple use case, removing a customer’s name before sending the text to an API may be enough. Serious AI applications, however, usually involve more than a name and a number. A medical record, inspection report or set of logs can reveal someone’s identity, a system’s weakness or an organization’s future decision without containing any explicit identifier. Conversely, if all meaningful clues are removed, the model that was supposed to reason about relationships and context no longer has enough material to produce a useful answer. Confidentiality when using a public API is therefore more than a security feature: it is a problem of where to draw the boundary between preserving meaning and preventing that same meaning from being disclosed.
Encrypting the communication channel hides data from an eavesdropper along the way, not from the service that must receive it for processing.
Public APIs: a new trust boundary for the organization
In this article, a public API does not necessarily mean a free service or a public chat interface. Any model API whose main processing takes place outside the organization’s controlled environment, on a provider’s infrastructure, creates a new trust boundary. API keys, TLS, access control and encryption in transit are essential. In a conventional architecture, however, encryption terminates at the provider, and the request text becomes available to its systems for inference.
Data leaving the organization does not necessarily mean the provider will misuse it. Many commercial services promise not to use API data for model training and offer controls over retention, processing location or human access. Nevertheless, three statements must be distinguished: “data is not used for training,” “data is not retained after processing,” and “the provider is technically unable to see the data.” For example, OpenAI’s current documentation distinguishes between not using API data for training, abuse monitoring logs and Zero Data Retention controls. Anthropic also specifies a standard retention period and separate exceptions for its organizational API. Google’s documentation shows that even the availability of zero data retention can depend on the model, feature and settings of each request. An appropriate policy therefore reduces risk, but is not equivalent to cryptographic confidentiality. (OpenAI, Anthropic, Google Cloud)
The trust boundary also extends beyond the model itself. A request may be recorded in an organizational proxy, logging system, observability tool, conversation memory, prompt cache, file store or ancillary service. In agent-based systems, web search, organizational tools and MCP servers join the processing chain, each with its own policies and access permissions. The vague statement “we gave the data to the model” can thus conceal a multistage chain of recipients and temporary copies of the data.
What exactly needs to remain confidential?
Before comparing methods, it is necessary to recognize that confidentiality is not limited to removing identifying information. A single document can contain several kinds of secrets at once: explicit identifiers such as a name or national identification number; sensitive values such as an amount, age or test result; relationships between people and events; semantic content such as a medical diagnosis, an intention to acquire a company or the existence of a vulnerability; and, finally, conclusions the model can infer by combining seemingly harmless data.
This distinction matters because each method addresses only part of the problem. Replacing a patient’s name hides their explicit identity, but a rare disease, place of residence and appointment date may still be enough to reidentify them. Altering a few numbers can conceal their actual values while distorting a financial analysis. Even the subject of a question may be confidential. For example, a request to assess the risks of merging with a particular company reveals important information about an organization’s future decision before any document has been attached.
Families of available methods
The available methods fall into several families, ranging from contractual commitments to computation on encrypted data. These methods are not complete substitutes for one another: each targets a different threat model. Some only reduce the likelihood of secondary use, some hide a specific part of the input, and others try to prevent the provider itself from seeing the content being processed.
Contractual and operational controls
This family includes commitments not to use data for training, retention limits, selection of a processing region, audit logging, restrictions on employee access and special enterprise agreements. Its main advantages are maturity and full compatibility with powerful public models, but it still relies on the provider’s commitments, processes and audits. During inference, the data remains present in a processable form on external infrastructure, even if no other use is permitted.
Minimization, de-identification and pseudonyms
In this approach, fields whose actual values the model does not need are removed or replaced with fabricated tokens before transmission. More precise methods can preserve an identifier’s format so the model can recognize the data type, then map the output back to the original identifier within a trusted environment. Prεεmpt is a research example in this family that distinguishes between format-dependent and value-dependent data. This approach is promising for specific identifiers, but removing names alone is insufficient when the secret lies in the overall meaning of a sentence or the relationship between several pieces of data.
Statistical perturbation and differential privacy
Instead of sending exact values, data can be modified through controlled noise, binning or differential privacy mechanisms. Under defined conditions, these methods offer mathematical guarantees. Those guarantees, however, apply specifically to the secret, privacy budget and adversary model established in the design. Stronger protection increases the possibility of changing the result, especially in auditing, medicine or incident analysis, where a small difference in a value can change a decision.
Semantic transformation or obfuscation
An emerging idea, sometimes called “semantic encryption,” transforms text locally into a different context with a similar logical structure, obtains a public model’s response, and maps it back to the original context. The Semantic Encryption paper provides a concrete example of this approach and shows how a small local model can act as an encoder and decoder. The attraction is compatibility with an ordinary text API. The word “encryption,” however, must not be misleading: changing the vocabulary or story is not, by itself, a standard cryptographic proof, and the logical structure, values or relationships may remain inferable.
Separating reasoning from execution on data
In some architectures, the public model sees only the structure of the problem, a data schema or synthetic examples, rather than real records. It generates the analysis instructions, query or program, while actual execution takes place in a trusted environment. This family can sharply reduce the export of raw data and is compatible with ordinary APIs. It is not always sufficient, however, for tasks that depend on close reading, understanding the subtleties of a case or discovering an unknown relationship in the data. Database schemas, field names and aggregate outputs can themselves reveal important organizational information.
Protected intermediate representations and split inference
Instead of sending raw text, part of the model runs in the client’s environment and a protected intermediate representation or embedding goes to the cloud for further processing. The research system NOIR illustrates this approach: the client retains the encoder and decoder, while the middle of the model runs in the cloud. The key point is that an ordinary embedding is not encryption and can be targeted by reconstruction attacks. This architecture also requires provider cooperation and splitting the model; it cannot simply be added to a conventional, closed text API.
Confidential computing and trusted execution environments
In confidential computing, data is processed inside a trusted execution environment, or TEE. Mechanisms such as attestation can provide greater assurance about the software and execution environment. Performance has moved this approach closer to practical use, and recent evaluations have examined running LLMs in CPU and GPU TEEs. Its protection nevertheless depends on the hardware implementation, trust chain, correct configuration and resistance to side channels. It is relevant to a public API only when the provider itself offers the capability. (Evaluation of TEEs for LLM inference)
Homomorphic encryption and secure multiparty computation
Fully homomorphic encryption, or FHE, allows computation to take place directly on encrypted data. Secure multiparty computation, or MPC, distributes processing among several parties so that no single party sees all the data. Cryptographically, this family comes closer to “inference without seeing the data,” but running large models with long sequences remains very expensive and complex. Recent research has increased the supported model sizes and input lengths, yet these methods require a specialized model implementation. Sending ciphertext to an ordinary GPT API will not produce a meaningful answer. (Example of FHE research for Llama-3-8B)
Comparing the methods at a glance
| Method family | Compatibility with an ordinary API | What does it mainly protect? | Basis of trust | Current practical status | Main limitation |
|---|---|---|---|---|---|
| Contractual controls, no training and retention limits | Full | Secondary use, retention and operational access | Legal and procedural | Mature | The provider receives the data during processing |
| Minimization, de-identification, pseudonyms and format-preserving encryption (FPE) | Full | Previously identified fields and identifiers | Technical and partly cryptographic | Practical | Sensitive meaning and relationships may remain |
| Noise and differential privacy | Usually possible | Defined values or features | Mathematical, within a specified threat model | Practical in limited applications | Direct trade-off between confidentiality and accuracy |
| Semantic transformation | Full at the text level | Vocabulary and explicit context | Model-based obfuscation | Research | No general cryptographic guarantee; meaning may leak |
| Separating reasoning from execution on data | Full | Raw records and operational details | Architectural | Practical for structured problems | Limited for open-ended text analysis and unknown relationships |
| Split inference and protected embeddings | None without changes to the service | Raw text and part of the output | Architecture, randomization and a local model | Research and specialized applications | Raw embeddings are not secure; host cooperation is required |
| TEEs and confidential computing | Only with provider support | Data in use, against the host | Hardware and attestation | Emerging but usable | Trust in hardware, implementation and side-channel controls |
| FHE and MPC | Incompatible with an ordinary API | Data content during computation | Cryptographic | Mainly research for large LLMs | Computational cost, latency and limitations on operations |
| Private or local deployment | Removes the public API from the problem | Data, model and processing chain | Direct organizational control | Mature, with infrastructure costs | Cost, maintenance and a possible gap with frontier models |
There is no absolute winner in this table, because a “level of protection” has no precise meaning without identifying the adversary. A method that helps prevent the accidental logging of people’s names is not necessarily resistant to a curious provider, an attacker with access to logs, or an analyst combining several sources to reidentify someone. Even formal guarantees usually apply to a limited scope, a particular data type and a set of assumptions.
Risks and limitations that often go unnoticed
Removing identifiers is not the same as removing meaning
The greatest risk is reducing confidentiality to detecting a few named entities. A personal information removal tool may correctly identify names and phone numbers, while an unusual job title, the date of an event and a contract figure together reveal the same person or organization. Research on semantic privacy emphasizes this gap: sensitive information can be implicit, contextual or inferable from a combination of passages without appearing as a specific string in the text. (Survey of semantic privacy in LLMs)
Every intermediary can fail
The sanitizer, small local model, pseudonym mapping and output restoration mechanism together form a new chain of software and models. If sensitive-data detection misses a single instance, that one error can carry the original text across the trust boundary. If the output mapping is wrong, the response may sound fluent but refer to a different person, amount or document. In such a system, confidentiality and correctness are inseparable, and a protection failure can directly cause a decision error.
Embeddings and encoding are not necessarily encryption
Converting text into token IDs, embeddings, a simple hash or a compressed representation may make it unreadable to a person. Being unreadable, however, is different from being confidential. Intermediate representations often preserve part of the input’s semantic structure because that is precisely what the model needs to use. If an attacker has the model, vocabulary or enough examples, reconstructing or inferring some of the original text may be possible. Sending raw embeddings should therefore not be presented as a confidentiality solution without analyzing potential attacks.
Protecting the input does not cover outputs and tools
Even if the input is well concealed, the model’s response can repeat a sensitive fact or infer it from the data. RAG and agent architectures introduce another risk: retrieved content can cause the model to send data to a tool or destination outside the intended path. Prompt confidentiality is therefore only one layer. Controls over output disclosure, tool access and conversation memory remain separate problems.
Security claims often extend beyond their threat model
A paper may show good results against an “honest-but-curious” adversary, while a real system faces a malicious provider, a compromised library, an employee with access, a side-channel attack or adaptive requests. Similarly, low lexical similarity between the original and transformed text does not prove that a sensitive concept, number or relationship cannot be inferred. A method’s name, the presence of equations and even good results on several benchmarks do not replace a precise definition of the secret, adversary and leakage criterion.
New features can change data policies
Persistent memory, files, longer-lived caches, background execution, web search and connections to third-party tools make APIs more useful, but each capability can introduce a different data path and retention period. The basic contract may be appropriate, yet enabling a particular endpoint or tool can move data into another store. Confidentiality cannot therefore be assessed once for a provider’s name alone: it must be evaluated for the actual model, endpoint, feature, region and configuration.
Moving beyond “Is the API secure?”
Dividing services into “secure” and “insecure” oversimplifies the problem. A more precise question is which part of the data must remain hidden, from whom, at which stage and with what degree of assurance, and how much loss of accuracy, latency and cost is acceptable in return. A public customer support system will not have the same answer as an application analyzing medical records, product source code or plans for a corporate merger.
Today, the options for confidential use of public models span contractual controls, data minimization, pseudonyms, statistical perturbation, semantic transformation, separation of tasks from data, split inference, trusted execution environments and cryptographic computation. Some are already practical but protect only a limited part of the secret. Others provide stronger guarantees but do not plug into a conventional API. Still others remain primarily research topics rather than generally available products. Recognizing these differences is the first step toward distinguishing “reducing the likelihood of disclosure” from “technically preventing the data from being seen.”
Follow-up articles in this collection can examine each family separately, from pseudonyms and differential privacy to semantic encryption, split inference, TEEs and FHE. At that stage, each method’s threat model, architecture, output quality, cost and security evidence should be assessed in detail. Before selecting a tool, however, the confidentiality problem itself must be defined correctly.