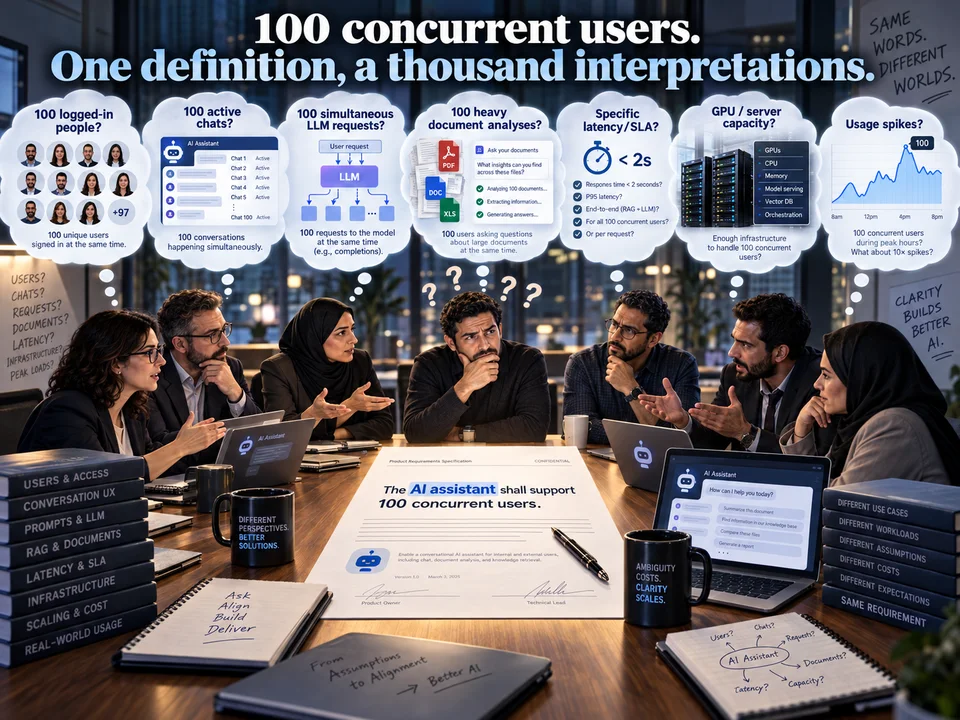
Imagine two companies requesting proposals for an enterprise AI assistant. Both state the same apparent requirement: “The system must support 100 concurrent users.”
The first wants staff to ask questions about internal policies and receive relatively short answers. The second expects staff to analyse documents hundreds of pages long, produce comparative reports and sometimes use several agents to complete a task.
Do they need the same infrastructure?
Even with exactly 100 users each, their processing requirements may differ severalfold. A fairly ordinary server might serve hundreds of people in the first company adequately, yet deliver unacceptable delays under just a few heavy requests from the second.
User count is not a unit of processing capacity. Capacity depends on request arrival rates, input and output lengths, processing type, concurrency patterns and the expected level of service.
The Persian field report on Targoman under roughly 300 concurrent requests illustrates this distinction. Service continued on one RTX 4090, but queues, slower responses and cancellations occurred. Continued operation was the observation; the number 300 alone does not establish a response-quality commitment for an enterprise assistant.
To make a useful model for choosing language models, GPU counts and infrastructure budgets, we need to work through what “concurrent users” actually means.
1. A hundred users are not a hundred requests
An enterprise system has at least four distinct counts:
- Connected users: people with an established session.
- Active users: people actually using the system during a defined interval.
- In-flight requests: submitted requests that have not completed, whether queued or processing.
- Running inferences: requests actually occupying inference-engine resources.
These counts need not be equal. A hundred people may be logged in, 30 may be reading earlier answers, ten may be waiting for a response and only six requests may be running on the GPU.
Even running-request count does not define the processing load. Six requests with 500 input tokens and 100 output tokens differ from six with 32,000 input tokens and 2,000 output tokens.
We need to model user behaviour rather than simply count users.
2. First calculation: how often does each user send a request?
Let be the active-user count and the average requests per user per minute. The arrival rate is:
Here is measured in requests per second. For 100 users:
| Usage pattern | Requests per user per minute | Total arrival rate |
|---|---|---|
| Light | 0.1 | 0.167 requests/s |
| Moderate | 0.5 | 0.833 requests/s |
| Heavy | 2 | 3.333 requests/s |
In the first case, each user sends a request every ten minutes on average. In the third, every 30 seconds. Both systems have 100 users; their arrival rates differ by a factor of 20.
This calculation still simplifies arrivals to an average. Real requests do not necessarily arrive at regular intervals: two might arrive during one minute, followed by 20 almost together a few seconds later. Peak-period behaviour and short bursts therefore need measuring alongside the average rate.
3. Second calculation: how much work is in each request?
Language-model requests usually have two main stages:
Prefill: processing input tokens, including the question, system instructions, conversation history and retrieved documents.
Decode: generating output tokens, usually incrementally.
Their computational behaviour differs. Prefill often depends more on parallel compute capacity; decode, especially at small batch sizes, can be sensitive to memory bandwidth.
The GPU selection guide and “Why the fastest GPU does not necessarily deliver the fastest response” examine this further. The latter distinguishes aggregate token rate from response-start and completion times. Here we begin with demand from users.
Suppose the system receives three request types:
| Request type | Input tokens | Output tokens |
|---|---|---|
| Simple question | 1,000 | 150 |
| RAG question | 8,000 | 500 |
| Multi-document analysis | 32,000 | 2,000 |
Assume they account for 70%, 25% and 5% of requests. Average input length is:
Average output length is:
At one request per second, input and output demand are:
These are token demand rates, not required GPU FLOPS or a server benchmark that can be promised to a customer. In particular, adding 4,300 input tokens to 330 output tokens does not establish a single capacity requirement of 4,630 tokens/s. The stages have different costs, which change with batching and context length.
At the same one-request-per-second arrival rate, each group contributes:
| Group | Share of requests | Input demand, tokens/s | Output demand, tokens/s |
|---|---|---|---|
| Simple | 70% | 700 | 105 |
| RAG | 25% | 2,000 | 125 |
| Analysis | 5% | 1,600 | 100 |
| Total | 100% | 4,300 | 330 |
These are illustrative demand figures, not measured GPU capacities. Just 5% of requests account for about 37% of input tokens. A small minority of heavy requests can consume a large share of prefill capacity.
4. Third calculation: how many requests will overlap?
Little’s law gives a useful relationship:
- : average requests present in the system.
- : average arrival and completion rate in steady state.
- : average time a request spends in the system.
At one request per second and an average completion time of eight seconds:
Eight requests are present on average. If response time rises to 20 seconds as load grows:
There are now 20 requests in the system without any change in user count or arrival rate.
These requests are not necessarily all running on the GPU. Some may be queued, others retrieving documents and others generating text. Little’s law relates throughput, requests present and time spent; it does not calculate GPU capacity. It also describes steady state rather than predicting sudden bursts on its own.
5. Fourth calculation: how does a queue make a fast system slow?
Consider a simple queue with arrival rate and service capacity . Utilisation is:
For an effective capacity of two requests/s and arrivals of one request/s, . At 1.9 requests/s, . Average capacity still exceeds arrivals, but very little headroom remains.
In the ideal M/M/1 model, average time in the system is:
For requests/s:
| Utilisation | Arrival rate, requests/s | Average time in system, seconds |
|---|---|---|
| 25% | 0.5 | 0.67 |
| 50% | 1 | 1 |
| 70% | 1.4 | 1.67 |
| 80% | 1.6 | 2.5 |
| 90% | 1.8 | 5 |
| 95% | 1.9 | 10 |
| 98% | 1.96 | 25 |
| 99% | 1.98 | 50 |
This relationship requires and M/M/1 assumptions. Actual vLLM latency must be measured under load. In this theoretical example, raising utilisation from 50% to 95% increases average time from one second to ten.
An LLM inference engine is not an M/M/1 queue. Continuous batching, scheduling, uneven token lengths and KV-cache management all make service capacity depend on the workload.
The example illustrates a principle rather than predicting actual latency: maximising GPU utilisation does not necessarily deliver the best service. An enterprise assistant needs an operating point where increasing load still respects the response-time requirement, rather than a target of 100% utilisation alone.
6. Fifth calculation: is there enough GPU memory for this concurrency?
Memory can run out before compute capacity is saturated. A rough memory budget is:
For a dense model with parameters stored at bits:
An 8-billion-parameter model with BF16 weights needs about 16 GB of raw weights. On an RTX 4090 with 24 GB VRAM, that does not make the entire nominal remaining 8 GB available for user requests: runtime structures and buffers also occupy memory.
Moreover, 16 billion bytes is about 14.9 GiB. Convert weights, cache and actual free device memory to the same unit. “What four-bit quantization makes cheaper, and what it changes” explains why shrinking weights does not shrink KV cache and serving overhead in the same proportion.
KV-cache memory
For a conventional transformer, approximate cache memory per token is:
Here is bytes per cache element. For an illustrative model with 32 layers, eight KV heads, head dimension 128 and BF16 cache:
That is about 128 KiB per live token. With 30 requests and 19,456 live tokens each, theoretical cache alone reaches 71.25 GiB, before model weights or engine overhead. Changing those two values shows why context length and concurrency belong in the same calculation.
Interactive tool: combine the model, GPU and request count
The tool’s illustrative model uses that architecture. Real packages take their weight-file sizes and model geometry from the LLM table. Choose GPU count and deployment, then move the sliders. If you have not selected hardware, candidates come from the site’s GPU list.
From user count to a memory budget
Which GPU can hold this workload?
Choose a model and workload. If you have not selected a GPU, the tool suggests candidates to test. A memory fit is an estimate; speed and service quality still need testing.
Memory assumptions and actual free space
Illustrative model: 8 billion parameters, raw BF16 weights, 32 layers, 8 KV heads and a head dimension of 128. Current geometry: 32 layers, 8 KV heads, head dimension 128.
The default 2 GiB reserve is the table’s planning assumption, not a measurement or an overhead ceiling. Quantized weights do not imply a low-precision KV cache: check engine support and cache accuracy separately. This full-attention estimate assumes no savings from prefix caching, sliding-window attention, MLA or hybrid architectures.
First candidate for comparison: 1 × GeForce RTX 5090
Fits the memory estimate
- Weights 14.9 GiB
- KV 8 GiB
- Reserve and other components 2 GiB
With balanced distribution, the busiest GPU is assumed to handle 8 requests. Each GPU loads the complete weights; queues and uneven distribution can change this estimate.
For initial screening, the table’s nominal memory class is treated as a GiB budget. Before deployment, enter the device’s actual free memory. The theoretical limit above does not establish capacity at an acceptable latency.
PCIe; board-partner dependent · Active · PCIe 5.0
Manufacturer specifications ↗GPU candidates to test
Candidates come from the site’s current GPU list, ordered by the fewest devices and then memory capacity. Price, speed and package compatibility with each engine still need checking. When more devices are needed, the suggested count appears beside the GPU name.
- 1 × GeForce RTX 509032 GB per GPU · estimated headroom 7.1 GiB
- 1 × RTX 6000 Ada48 GB per GPU · estimated headroom 23.1 GiB
- 2 × GeForce RTX 4090 D24 GB per GPU · estimated headroom 3.1 GiB
Suggestions exclude announced products, unofficial boards, unified system memory and pooled multi-chip capacity. For AMD and Intel, check package, kernel and engine support on the exact model and operating system.
Explore user load and token demand
- User requests per second
- 0.833
- Model calls per second
- 0.833
- Input demand, tokens/second
- 3,583.33
- Output demand, tokens/second
- 275
- User requests in flight; Little’s law
- 6.67
In steady state, Little’s law includes the queue and all workflow stages. It does not automatically set the running-inference slider. Input and output are counted separately; the assumed response time is not a prediction by this tool.
Demand divided by measured capacity: Prefill Needs testing; Decode Needs testing.
These ratios are only an initial screen. Stage interference, P95, bursts and goodput need testing under a mixed workload. Enter measured capacity for the entire configuration; the tool does not multiply speed by GPU count. Changing the model, deployment or request length clears the measurements so you can enter results for the new settings.
With independent replicas, each GPU holds the complete model and requests are distributed between them. With model splitting, the tool shows an ideal evenly divided budget; per-device memory, engine support and communication must be checked separately. “PCIe or SXM: interfaces in AI infrastructure” explains the hardware paths.
The example depends on its stated architecture. Different GQA layouts, MLA or hybrid attention have different memory behaviour. Paged KV cache and prefix caching can also change allocation and sharing.
Concurrency and context length compete for memory. A configuration that serves many short requests can reach its limit with just a few 32K-context requests.
7. Sixth calculation: one user can trigger several model calls
An agentic assistant complicates the relationship between users and requests. A user asking it to review five contracts, identify conflicting clauses and write a report may trigger multiple model calls, some sequential and some parallel.
If a user request generates an average of model calls:
At one user request/s and four model calls per request:
Call count alone is still insufficient. Their lengths may differ greatly, and one stage’s output can become the next stage’s input. Capacity planning must consider the execution graph, dependencies, opportunities for parallelism and each stage’s token volume.
| Stage | Dependencies and possible execution pattern |
|---|---|
| Extract information from each contract | Several calls; independent documents may run in parallel |
| Check conflicts | Depends on extracted information |
| Retrieve regulations | May run alongside extraction or after identifying the issue |
| Combine results and write the report | Depends on earlier outputs |
Each stage may contain several calls. This is a workflow example, not a fixed call count. A 100-user question-answering chatbot’s capacity cannot be transferred directly to an agentic assistant.
8. How do we estimate actual capacity?
For an initial estimate, use service demand. For request class , let be its request share and its equivalent resource-occupation time on a reference configuration:
In a simple single-resource model with fixed service capacity:
This is only an approximation for LLM inference: batching can change per-request cost, and prefill and decode consume resources differently. A more useful technical screen evaluates several dimensions separately:
and are measured capacities under a reference workload, not raw FLOPS or memory bandwidth. The ratios are screening approximations and do not fully model interference between stages.
Document retrieval, reranking, CPU, RAM, networking and storage need separate assessment. The guide to choosing a language model, embedding model and reranker distinguishes their responsibilities. Placing them on one GPU requires a shared memory and service-time budget. Retrieval latency can spoil the user experience even while the LLM engine has spare capacity.
9. The final measure is acceptable responses
Suppose two configurations each complete 1,000 requests in ten minutes. In the first, 970 meet the specified response-time and quality requirements; in the second, only 700 do.
Both have the same throughput:
Their goodput differs:
The first provides more useful service even though the raw completed-request count is identical.
The comparison of Ollama, vLLM, SGLang and llama.cpp also connects engine choice to service and deployment conditions. GenAI-Perf’s metric definitions provide a starting point for specifying measurements.
Record time to first token (TTFT), token-production intervals (TPOT/ITL), response-completion time (E2E), P95 and P99, error rate and goodput. A contract’s “response time below three seconds” is ambiguous: three seconds to display the first token differs greatly from three seconds to generate a 500-token answer.
10. Turn “100 users” into a defensible test
Define a workload matrix rather than a single scenario:
| Scenario | Active users | Workload | Test objective |
|---|---|---|---|
| Normal use | 100 | Short questions and RAG | TTFT and goodput |
| Peak period | 100 | Bursty arrivals | P95 and queue growth |
| Heavy analysis | 25 | Long context and detailed output | Memory and E2E |
| Agentic tasks | 25 | Multi-stage calls | Entire workflow capacity |
| Mixed load | 100 | All groups combined | Stability and SLOs |
This is a proposed test plan, not an actual product specification. For each row, specify arrival rate, input/output length distributions, model and version, inference engine, cache state, latency limit and test duration.
Increase arrival rate step by step until a defined requirement is violated. Success must mean meeting quality and timing requirements: an incorrect or late response does not count as goodput.
For multi-user service, pair capacity testing with session-isolation testing. As the session and cache isolation section explains, correct queues and throughput do not prove isolation between users’ contexts. Use a distinct identifier or canary for each user, with caching enabled in the target configuration. Seeing another user’s content must stop the test.
Usable capacity can then be defined as:
It is the highest sustained arrival rate that meets all service-quality requirements for the stated workload mix, configuration and test conditions. This is far more precise than “supports 100 concurrent users.”
11. Do 100 users need an H100?
The information so far cannot support a defensible answer. A small quantized model on a midrange GPU may suffice for light use. A large model with long context may require several accelerators. The best design might route routine questions to a small model and analytical requests to a stronger one.
Hardware selection should follow workload definition. As the language-model selection guide explains, a larger model is not necessarily a better choice. It must achieve the required quality while remaining usable at real-world speed, memory and cost.
“What model size does each task actually need?” discusses that division of work. This page’s tool screens the memory requirement; language quality and task performance still need comparison on the organisation’s own examples, including Persian where required.
Cost can also be expressed per successful request rather than as the GPU purchase price:
Hourly cost should include depreciation, electricity, cooling, maintenance and infrastructure. Configurations with very different purchase prices and nominal performance can offer similar economic value per acceptable response, or reverse their apparent ranking.
What should a contract promise instead of “100 users”?
That phrase alone cannot select a GPU, estimate cost or define technical acceptance. An engineering commitment must state the usage pattern, request mix, context and output lengths, model, timing and quality requirements for those users.
Record them alongside model and engine versions and test settings in the acceptance criteria. “AI contracts: what exactly should we receive?” connects these requirements to project deliverables.
Instead of asking “How many users can this server support?”, ask:
Under what conditions can this system complete how many useful requests, at what quality and cost?
Both the buyer of an assistant and the company committing its product’s capacity to a customer need an answer.
Technical references for testing and implementation
- NVIDIA GenAI-Perf metrics: response-start and completion times, token intervals and request rate.
- vLLM configuration and optimisation: KV shortages, preemption and recomputation, chunked prefill and model splitting.
- vLLM parallelism strategies: model splitting versus replicas processing independent batches.
The figures in this article are worked examples. A customer commitment requires testing the exact model, weight package, engine, hardware and workload mix.